Transcribe as people speak
Use streaming speech input in an application.
From spoken words to useful text.
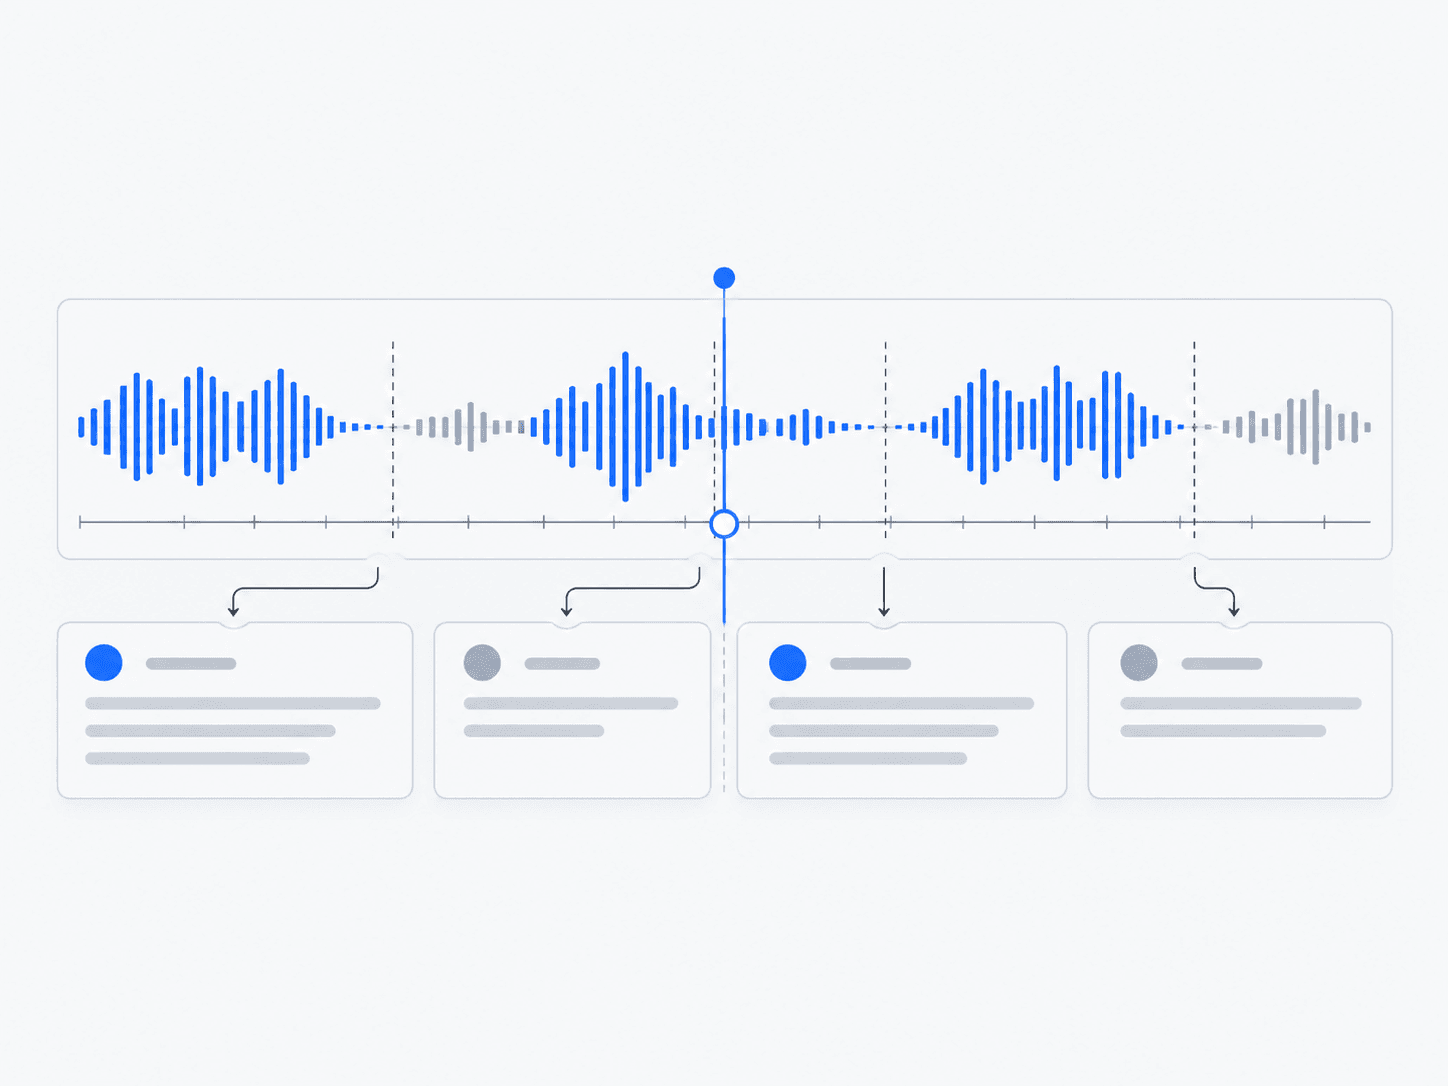
Muse Voice Transcribe is Meta's speech-to-text model. Applications access it through Model API, an interface for sending audio and receiving text, with streaming and file transcription, speaker labels and detection of speech turns.
Use streaming speech input in an application.
Turn audio files into transcripts for review.
Use speaker labels and turn-level timing where supported.
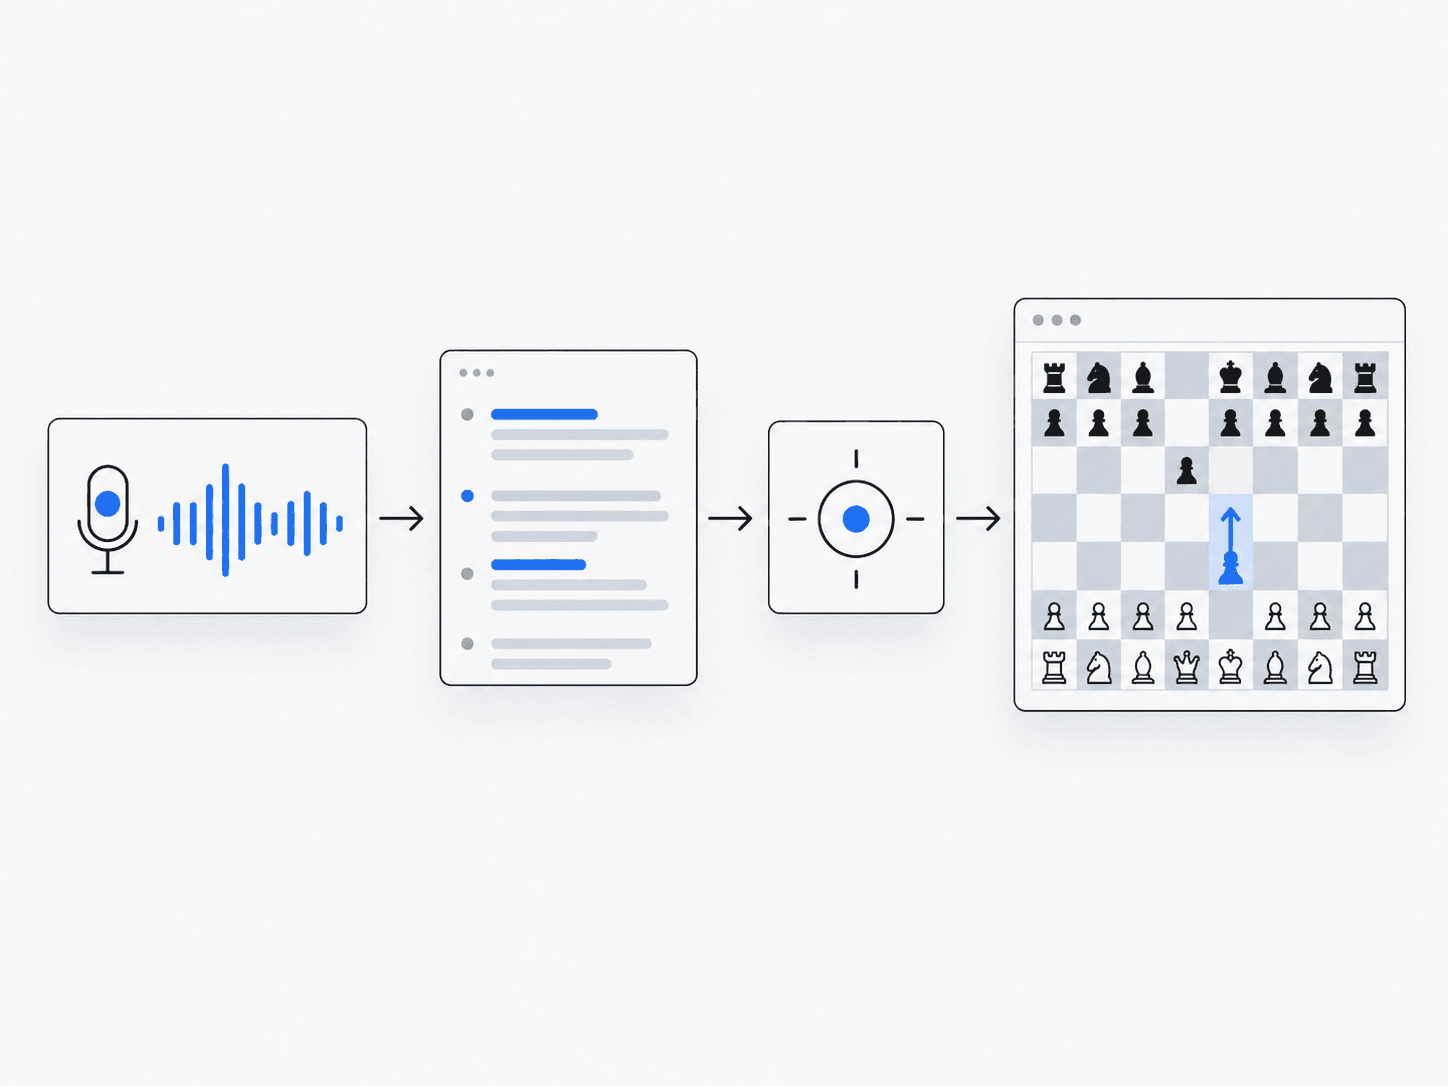
See where transcription ends and application reasoning begins.
Can we review the prototype tomorrow?
Speech is converted into text.
Yes. Let’s make it ten in the morning.
A new turn can be attributed to another speaker.
Proposed task: review prototype tomorrow at 10:00.
An application can interpret the transcript. Voice Transcribe itself does not schedule the meeting.
Voice Transcribe turns audio into text. Spark or your application can interpret that text and choose an action. Voice Transcribe itself does not generate speech.
Audio is sent to Meta Model API over realtime WebSocket or file upload endpoints. The model returns transcript text with turn-level timing and optional speaker labels.